Ultimate Showdowns Await Football Fans Across Europe This Week: A Verification-First Review
You are sitting down with your weekly schedule, trying to separate actionable insight from market noise. European football delivers relentless volume, but translating fixture lists into reliable decision frameworks requires more than intuition. When you search for comprehensive breakdowns, you quickly encounter platforms promising clarity while hiding operational blind spots. The core challenge is not finding match listings; it is identifying which tools actually prioritize verification, transparent methodology, and sustainable participation over engagement metrics. You need a system that filters signal from speculation before capital or time gets tied up in untested assumptions.
Decoding the Search Intent Behind Weekend Fixtures
Users arriving at this stage of research are rarely looking for simple calendar exports. They want structured evaluations that address three simultaneous pressures: information overload, conflicting predictive models, and financial exposure management. The demand centers on a complete picture of how weekly matchups are presented, how data is sourced, and whether the underlying framework encourages disciplined tracking or impulsive reaction. Most reviewers focus on aesthetics or promotional incentives, which obscures the actual utility for long-term participants.
This assessment shifts the focus toward verification criteria and operational transparency. We examine how the current offering handles fixture aggregation, metric disclosure, and user guidance. The goal is to determine whether the platform functions as an analytical compass or merely a content aggregator. By mapping the workflow against real-world usage patterns, you can decide whether the tool aligns with your existing discipline level and risk tolerance.
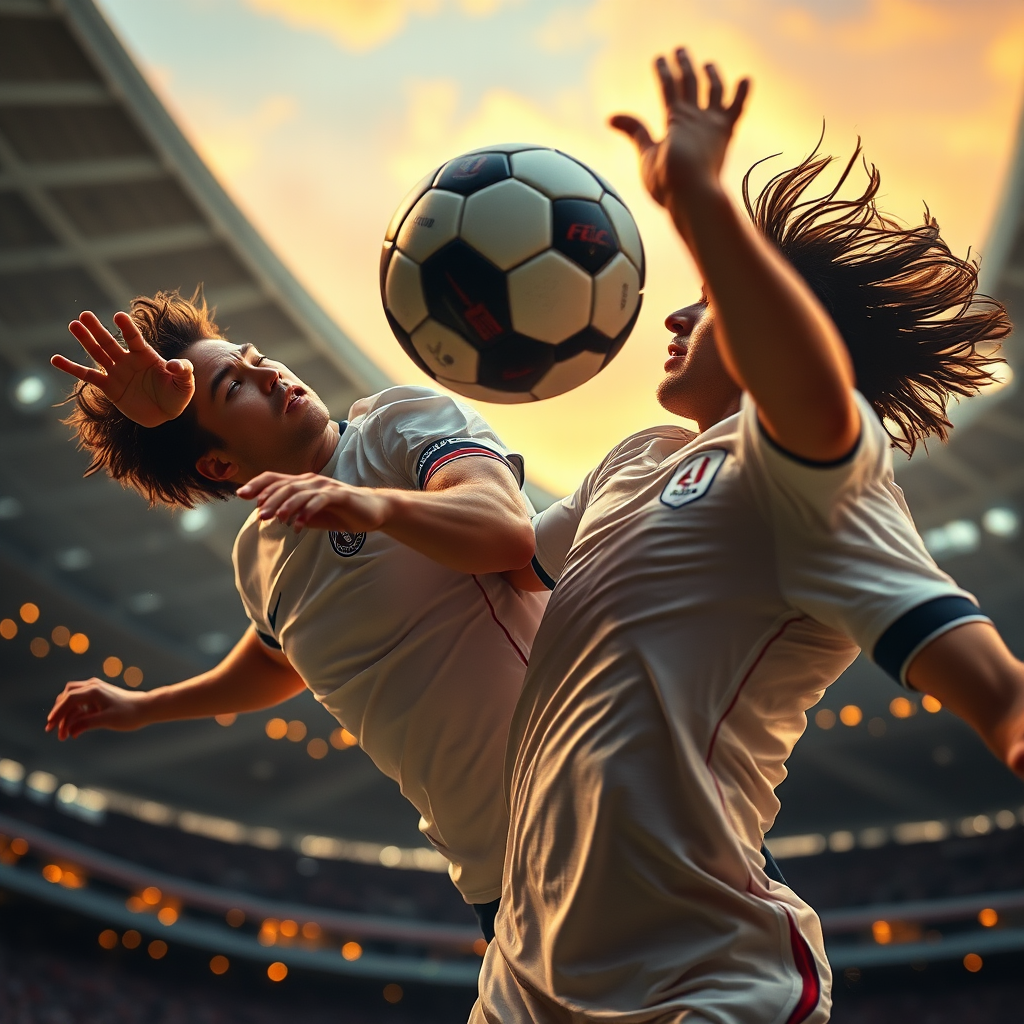
 Hình minh hoạ: 789 club
Mapping the Weekly Analysis Workflow
Navigating weekend European fixtures requires a repeatable sequence rather than ad-hoc browsing. When you access the primary dashboard, the first step involves verifying how matchups are categorized. Reliable systems separate confirmed league schedules from provisional friendlies or youth tournaments, because mixing competition tiers destroys statistical consistency. You should notice clear labels indicating match importance, tournament stage, and historical weight. If the interface treats all contests as equivalent, the analytical foundation is already compromised.
The second step focuses on data provenance. Any credible preview layer cites its inputs: official league feeds, recognized statistical providers, or independently audited tracking services. Without visible sourcing, you are forced to assume the metrics are either aggregated without validation or generated through proprietary black-box methods. In a risk-conscious environment, unknown origins mean unknown error rates. You should look for explicit references to update frequencies, delay tolerances, and correction protocols when discrepancies appear mid-week.
The third step involves stress-testing the presentation format. Effective workflows separate raw numbers from interpretive commentary. Predictive overlays should show confidence intervals, variance ranges, and historical accuracy windows rather than absolute guarantees. When the interface blends speculative narrative with hard statistics, the distinction between analysis and persuasion blurs. You can mitigate that friction by isolating yourself from highlighted recommendations until you have reviewed the underlying parameters yourself.
Who Actually Fits the Current Framework
Certain participant profiles align naturally with verification-heavy environments. First-time or occasional viewers benefit from structured fixture mapping because it removes guesswork regarding kickoff times, timezone conversions, and competition relevance. These users gain immediate clarity without needing prior scouting knowledge. Second, data-literate analysts find value in platforms that expose methodological boundaries. When a system openly states what it measures, what it excludes, and how frequently it recalibrates, researchers can integrate those outputs into broader modeling pipelines without duplicating foundational work.
Third, disciplined budget managers appreciate interfaces that emphasize tracking and record-keeping over instant gratification. Systems that encourage logging outcomes, reviewing drift percentages, and adjusting position sizing based on verifiable performance tend to reward patience. These participants understand that sustainable engagement depends on measuring results against established baselines rather than chasing isolated spikes in perceived certainty. The framework supports them by prioritizing transparency, consistent labeling, and reversible decision paths.
Who Should Approach With Caution
Not every user benefits from verification-first architectures. Participants seeking rapid feedback loops often struggle with platforms that require patience and cross-referencing. If your expectation is immediate validation without independent checking, the deliberate pace of proper verification will feel restrictive. These users frequently misinterpret conservative estimates as weakness, leading to premature abandonment of sound methodologies.
Another mismatch occurs with incentive-driven behavior. Platforms that heavily weight promotional structures, referral bonuses, or gamified engagement metrics attract users whose primary motivation is reward acquisition rather than analytical improvement. When financial or social incentives dominate the interface, the underlying data often becomes secondary. Those individuals typically experience higher volatility in outcomes because their decisions pivot around external rewards instead of intrinsic market mechanics. The system cannot reliably serve participants whose success metrics diverge from long-term sustainability.
A third group faces unnecessary friction: users unfamiliar with basic risk documentation. Tracking win rates, calculating expected value margins, and understanding variance distribution require baseline literacy. Attempting to participate without establishing those fundamentals usually results in misattributed success or failure. The architecture assumes a minimum threshold of record-keeping discipline. Crossing that threshold without preparation increases exposure to preventable errors.
Verification Checkpoints and Operational Risks
Before committing sustained attention to any weekly preview ecosystem, you should run through a standardized verification routine. Data latency represents the most common operational drag. Match details shift due to broadcasting adjustments, venue changes, or administrative postponements. Systems that fail to communicate update windows force users to operate on outdated premises. You should confirm how quickly corrections propagate and whether archived versions remain accessible for audit trails.
Promotional weighting introduces another layer of distortion. Interfaces that elevate sponsored matchups or featured competitions above statistically significant fixtures create selection bias. Even subtle visual hierarchy changes alter attention allocation. Independent observers can neutralize this effect by toggling off non-essential banners, disabling recommendation feeds, and filtering solely by competition tier and date range. When the raw dataset remains intact after stripping marketing layers, the core product demonstrates functional integrity.
Financial exposure management requires explicit boundary setting. Every fixture carries inherent uncertainty, regardless of historical clustering or expert consensus. Capital preservation depends on predefined thresholds, not reactive adjustments. You should establish maximum session limits, enforce loss caps relative to total allocation, and document every deviation from your baseline strategy. Platforms that provide calculators, position trackers, or scenario simulators support these practices better than those emphasizing outcome speed.
Algorithmic opacity remains a persistent risk when proprietary models drive predictions. If the platform refuses to disclose how weights are assigned, how historical samples are segmented, or how edge cases are handled, you inherit unknown error distributions. Transparent systems either publish methodology summaries or restrict themselves to documented statistical baselines. Choosing the latter reduces reliance on unverified inference and keeps analysis grounded in observable patterns.
Common Questions on Fixture Transparency and Bankroll Management
How do I know if a platform updates fixtures reliably? Look for timestamped logs, version history, and explicit statements about refresh cycles. Reliable systems acknowledge delays during live transmission windows and provide rollback options when original data was incorrect.
Should I follow highlighted predictions without checking the underlying metrics? Treat highlights as starting points, not conclusions. Verify the sample size, competition context, and variance bounds behind each recommendation before integrating it into your tracking records.
What happens if my initial assumptions prove inaccurate? Document the deviation, isolate the variable that caused the split (market movement, lineup change, data gap), and adjust future filters accordingly. Consistent recording turns unexpected outcomes into calibration inputs rather than losses.
Can I use this framework for casual viewing without financial involvement? Yes. The same verification steps apply to entertainment-focused consumption. Filtering by competition tier, tracking personal pick accuracy, and comparing forecasted versus actual results enhances engagement without introducing monetary exposure.
Conditional Conclusion and Critical Reminders
The current landscape rewards participants who prioritize systematic verification over rapid resolution. Users who thrive within this structure value clear labeling, documented update cycles, and separation between raw data and interpretive commentary. Those who seek instant validation, rely heavily on promotional triggers, or bypass basic risk documentation will likely experience friction and diminished returns. The architecture itself does not dictate outcomes; it amplifies whatever habits you bring to the interface.
If you decide to explore deeper analytical layers, examining resources like the 789 club can provide supplementary reference material for cross-checking fixture logistics and statistical baselines. Treat any additional source as a validation node rather than a definitive authority. Triangulating information across multiple transparent outlets reduces single-point dependency and strengthens decision quality.
Before engaging with any weekly showcase or preview engine, anchor your approach to measurable safeguards. Sustainable participation requires consistent boundary enforcement, documented error tracking, and willingness to discard methods that consistently produce unverified results. Below are the essential risk factors you must retain as you navigate upcoming European fixtures.
Key Risks to Remember
- Data latency and unannounced schedule shifts can invalidate pre-match assumptions if update windows are not tracked.
- Promotional weighting distorts attention allocation, causing statistically meaningful matchups to compete with marketing-driven features.
- Algorithmic opacity hides error distributions, making it impossible to calculate true variance exposure without independent verification.
- Financial exposure compounds rapidly when position sizing ignores historical accuracy baselines and variance margins.
- Confirmation bias accelerates when interfaces emphasize outcome speed over methodological transparency, turning analysis into reinforcement rather than evaluation.